AI on Edge
Recently, I happened to deploy d3 and qwen 3.5 on my own infra.
One is a System One decision model that specializes in giving structured probabilistic outputs for software, while the other is a System Two model that we are all familiar with.
With this deployment, I was able to achieve unlimited usage of the models for all intents and purposes.
Along with that, the generation quality of outputs was good.
The craziest thing is that each model runs on a single OCPU and within 2 GB of memory.
Some technical details if you care:
- Inference engine: llama.cpp
- Base Model: d3-nano, qwen3.5:0.8b
- Quantization: Q4_K_M
- Time to decision: ~10-15s
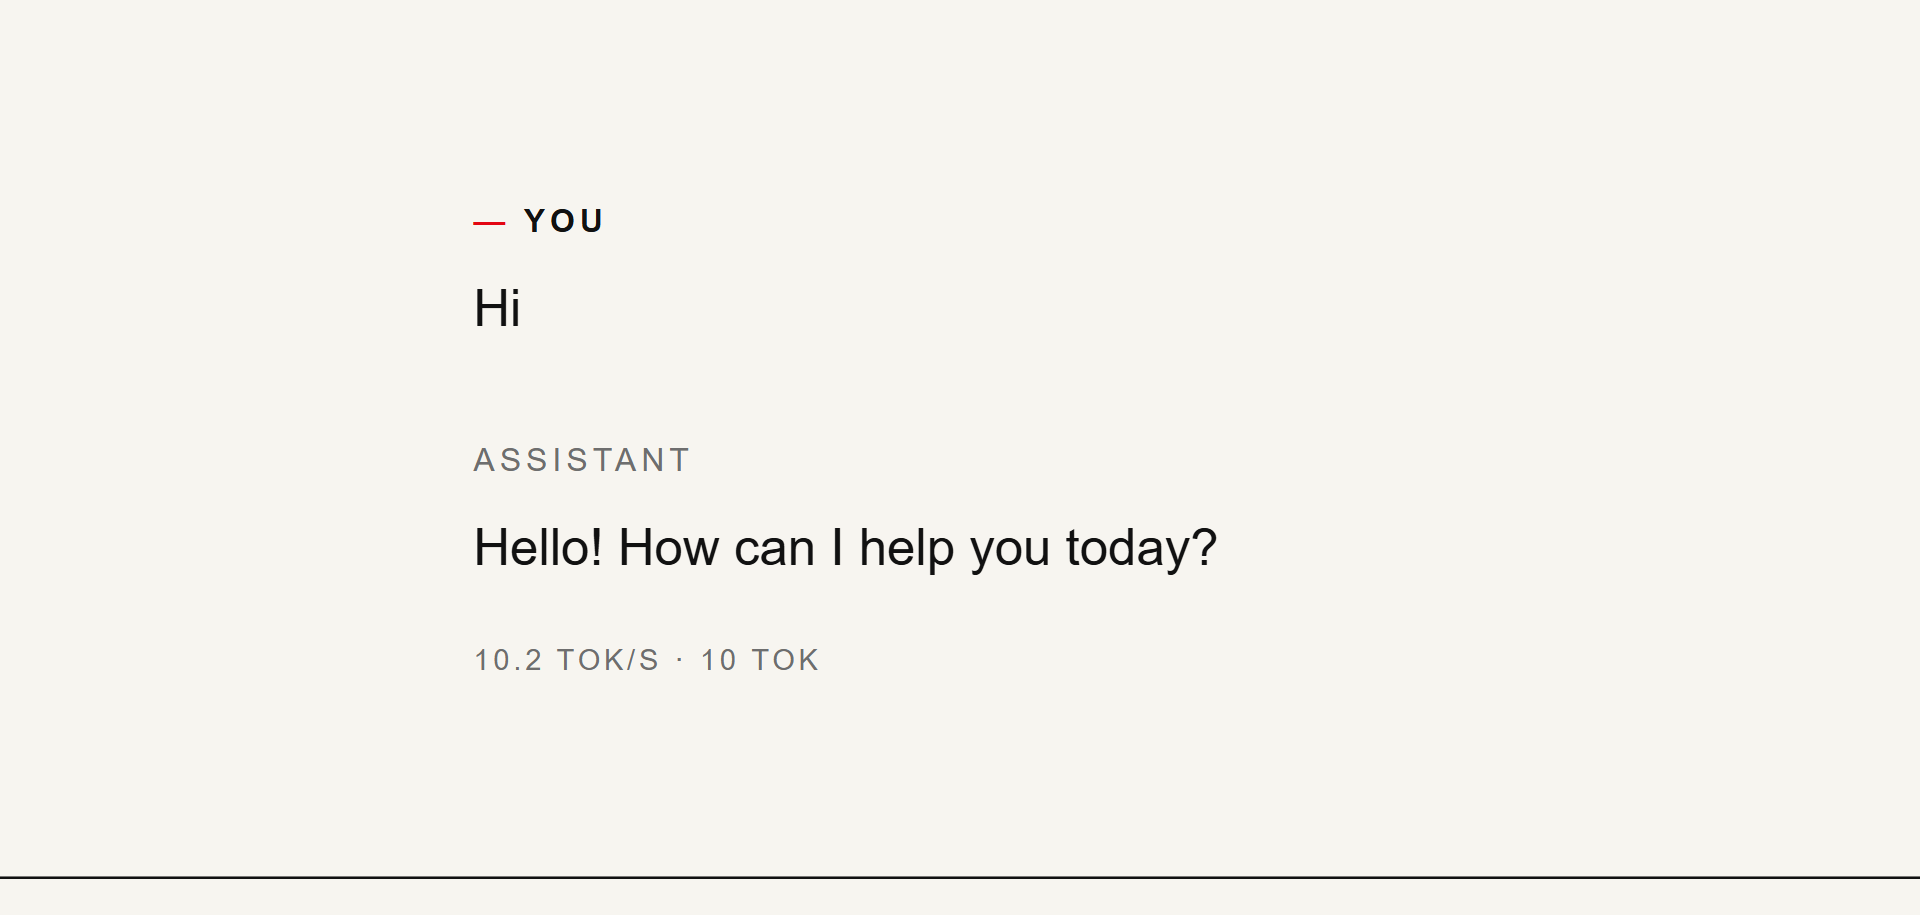
- Tok/sec: ~9-10
Got them both working in a UI as well: https://llm-ui.shares.zrok.io/
It's good to know how to deploy these on your infra, given that you can always deploy bigger models later.
Comments
Join the discussionNo comments yet. Be the first to comment.